A practical guide for data engineers and architects: a five-step diagnostic to find what is actually slow, followed by ten query-level techniques that fix it without buying more compute.
Why bigger is not always faster
When a Snowflake query runs slowly, the knee-jerk reaction is to upsize the warehouse. Medium (4 credits/hr) to Large (8) to X-Large (16) feels like a quick fix, and often the query does finish sooner. But every size step doubles the cost, and if the root cause is not resource starvation the return diminishes fast.
Each added node brings CPU, memory and local SSD cache. That only helps queries limited by one of those. It does nothing for queries that are slow because of:
- Scanning too much data: poor pruning reads terabytes the query never needed.
- Exploding joins: a bad join condition multiplies rows, and no compute makes that cheap.
- Waiting in a queue: the query is not slow, it has not started yet.
- Compilation overhead: deeply nested views can spend seconds just planning.
- Data skew: one node does most of the work while the rest sit idle.
Part 1 · 1. Triage: queue time vs. execution time
If a user says a query took 15 minutes, first ask: was it executing, or waiting? ACCOUNT_USAGE views can lag by up to about 45 minutes, so for a query that just ran use INFORMATION_SCHEMA.QUERY_HISTORY() instead.
					SELECT query_id, user_name, warehouse_name, warehouse_size,
       execution_time / 1000            AS execution_s,
       queued_provisioning_time / 1000  AS queued_provisioning_s,
       queued_overload_time / 1000      AS queued_overload_s,
       compilation_time / 1000          AS compilation_s,
       total_elapsed_time / 1000        AS total_s,
       partitions_scanned, partitions_total,
       bytes_spilled_to_local_storage, bytes_spilled_to_remote_storage
FROM   snowflake.account_usage.query_history
WHERE  execution_status = 'SUCCESS'
  AND  start_time >= DATEADD('hour', -24, CURRENT_TIMESTAMP())
ORDER  BY total_elapsed_time DESC
LIMIT  50;
| Phase | What it means | Does a bigger warehouse help? |
|---|---|---|
| Queued | Waited for capacity or for the warehouse to resume. | Sometimes. High QUEUED_OVERLOAD_TIME is a concurrency problem: scale out (multi-cluster, Enterprise+), not up. |
| Compilation | Parsing and planning. | No. Simplify the SQL or views. |
| Execution | Scanning, joining, aggregating. | Maybe. Depends what inside is slow. |

2. Spotting spilling in the Query Profile
If execution time dominates, open the Query Profile and check spilling first.
| Spill type | Impact | Action |
|---|---|---|
| Local storage | Moderate, noticeable slowdown. | Tighten predicates, reduce join explosion, or go up one size. |
| Remote storage | Severe, often an order of magnitude slower (network I/O). | Rewrite now: fix Cartesian joins, drop unnecessary SORT/DISTINCT, prune early. |

3. Partition pruning: clustering keys vs. Search Optimization
If partitions scanned is close to partitions total, Snowflake is doing a full table scan. Find the offenders:
					SELECT query_id, partitions_scanned, partitions_total,
       ROUND(partitions_scanned / NULLIF(partitions_total, 0) * 100, 1) AS pct_scanned,
       bytes_scanned / POWER(1024, 3) AS gb_scanned
FROM   snowflake.account_usage.query_history
WHERE  start_time >= DATEADD('day', -7, CURRENT_TIMESTAMP())
  AND  partitions_total > 1000
ORDER  BY pct_scanned DESC
LIMIT  25;
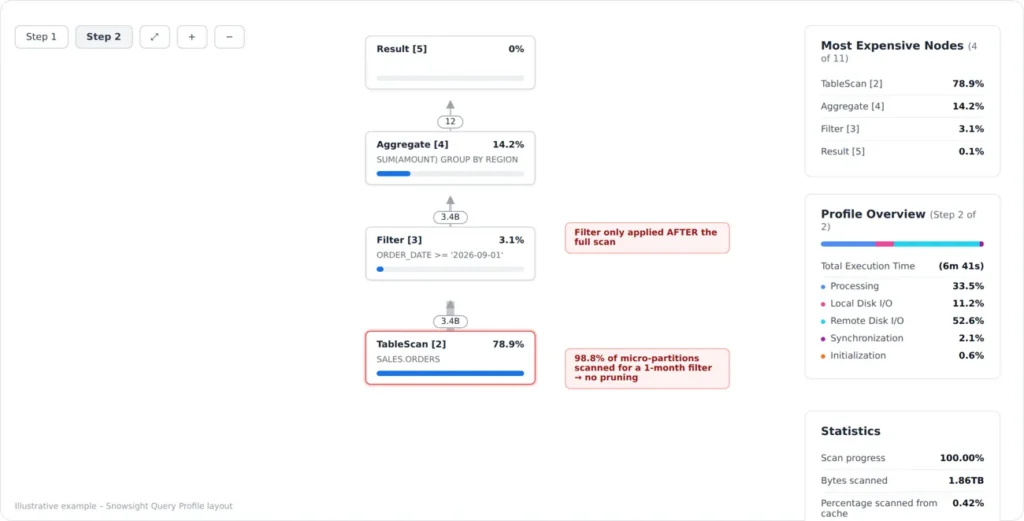
Option A: Clustering keys
Clustering physically reorganizes rows into micro-partitions by the chosen columns.
- Best for: date/timestamp ranges and medium-cardinality equality filters, plus group-by and join keys over thousands to millions of rows.
- Cost: Automatic Clustering consumes background credits as data arrives.


Option B: Search Optimization Service (SOS)
SOS builds a persistent search index next to the micro-partitions without reordering rows.
- High-cardinality point lookups: 1 to 100 rows out of billions (
WHERE transaction_id = '65878875'). - Substring and wildcard search:
LIKE '%pattern%',STARTSWITH, regex. - Semi-structured and geospatial: VARIANT paths,
ST_DWITHIN. - Many access paths: a table can be clustered one way, but SOS can index several independent columns (VIN, IP, email).
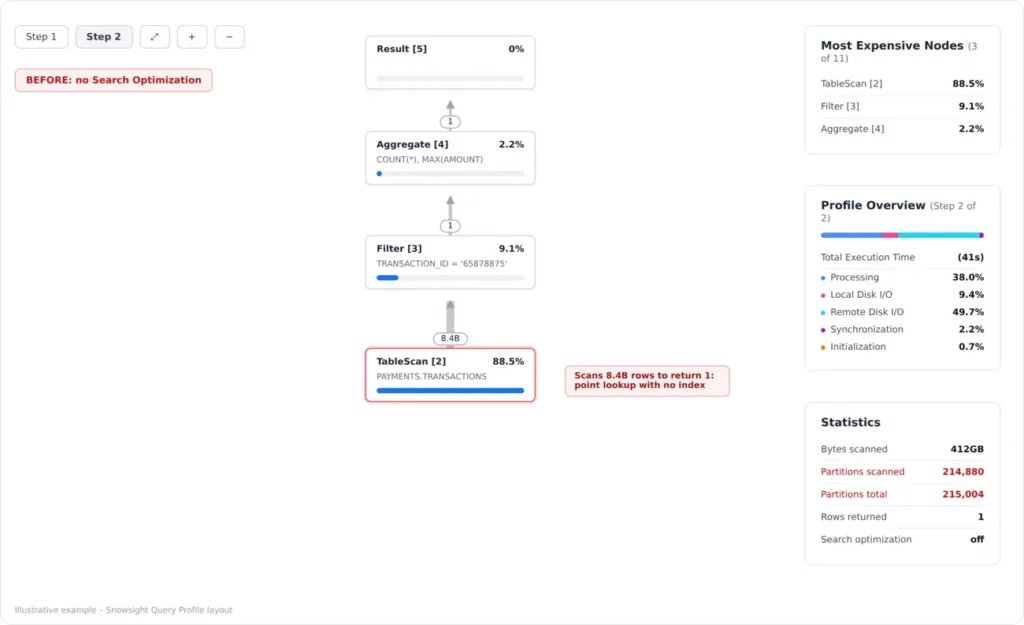

| Criteria | Clustering Keys | Search Optimization |
|---|---|---|
| Target | Range scans, batch reads, aggregations | Point lookups |
| Cardinality | Low to medium (dates, regions) | Very high (UUIDs, emails, IDs) |
| Filters | >, <, BETWEEN, IN | =, LIKE ‘%abc%’, VARIANT |
| Result size | 1,000s to millions of rows | 1 to ~100 rows |
| Mechanism | Reorders data | Secondary index structures |
| Paths per table | One | Many |
| Cost / edition | Clustering compute (all editions) | Maintenance compute + index storage (Enterprise+) |
					ALTER TABLE sales.orders CLUSTER BY (TO_DATE(order_ts), region);

ALTER TABLE sales.orders ADD SEARCH OPTIMIZATION
  ON EQUALITY(customer_id, order_uuid),
     SUBSTRING(customer_email);
event_date for range pruning and add SOS on device_id or ip_address for instant lookups inside those dates.4. Identifying join explosions
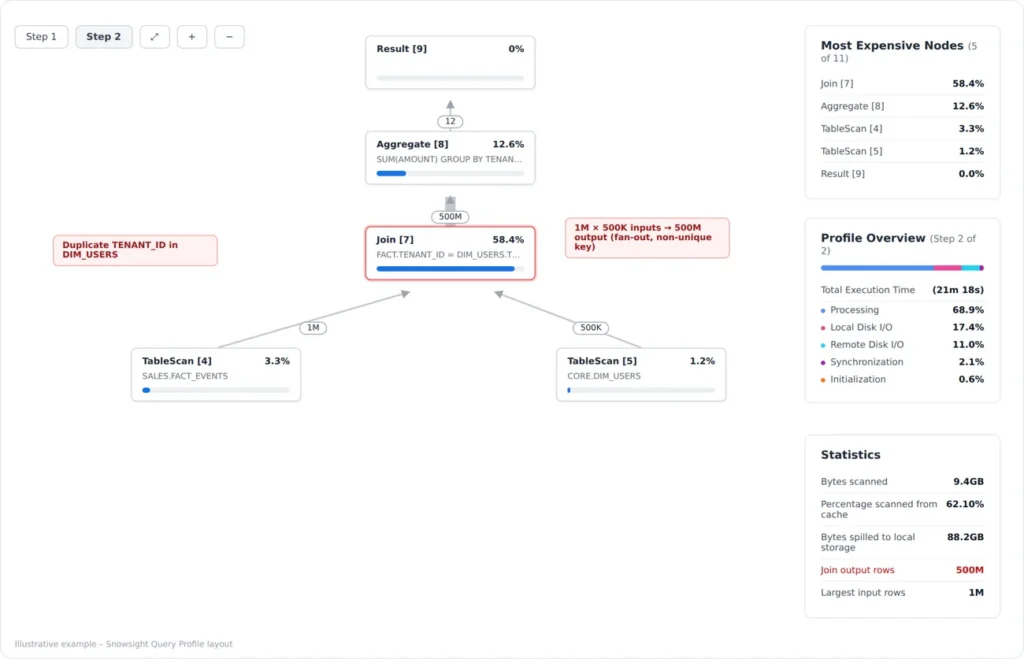
A join explosion outputs far more rows than it takes in, because of non-unique keys or a missing predicate. In the Query Profile, inspect the Join node: 1M rows joined with 500K rows should not return 500M. No warehouse size fixes a data modeling bug.
					SELECT tenant_id, user_id, COUNT(*)
FROM   dim_users
GROUP  BY 1, 2
HAVING COUNT(*) > 1;   -- duplicate keys fan out every join
5. Diagnostic checklist and flowchart
| Step | Question | If yes |
|---|---|---|
| 1 | Is QUEUED_OVERLOAD_TIME > 30% of total? |
Do not size up. Use multi-cluster auto-scaling (Enterprise+) or tune MAX_CONCURRENCY_LEVEL. |
| 2 | Is remote spill > 0? | Cut memory use in joins and aggregations. Upsize last. |
| 3 | Partitions scanned > 80% on a large table? | Clustering (ranges) or SOS (point lookups). See Part 2, techniques 2 and 3, too. |
| 4 | Join output 10x larger than input? | Fix join logic or duplicate dimension keys. |
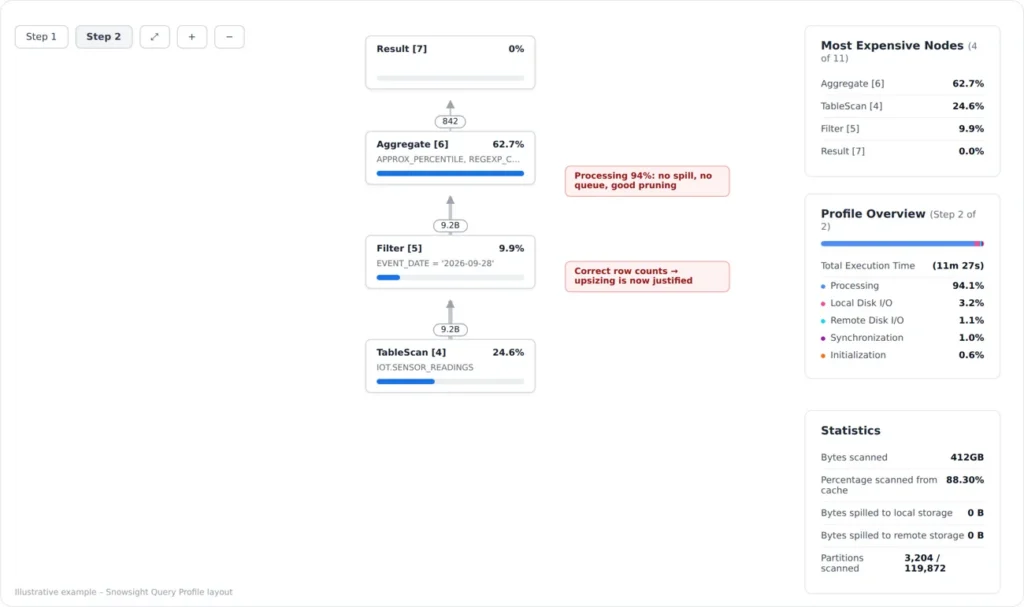
| 5 | Pure CPU on high data volume? | Upsizing is justified. Check skew and consider Query Acceleration Service first. |

Part 2 · Ten query-level optimizations
The diagnostic tells you which resource is the problem. These ten techniques change the SQL itself. Treat each as a hypothesis, and confirm with the Query Profile that bytes scanned, spill, or runtime actually dropped.
Stop reading columns you never use
Snowflake stores data in columns, so it reads only the columns you reference. SELECT * on a wide table (or one with large VARIANT columns) pulls far more bytes through scan, join and sort, and can push a query into spilling.
					-- Instead of SELECT * FROM rides.trips
SELECT trip_id, rider_id, fare_amount FROM rides.trips;

-- If you truly need almost everything
SELECT * EXCLUDE (gps_trace, device_json) FROM rides.trips;
bytes_scanned in Query Profile should fall roughly in proportion to the columns dropped.Filter so Snowflake can skip partitions
Filters on well-clustered or naturally ordered columns let Snowflake skip whole micro-partitions using min/max metadata. Wrapping the column in a function often hides that metadata, so filter on the raw column with a range.
					-- poor pruning: function applied to the column
WHERE TO_CHAR(pickup_ts, 'YYYY-MM') = '2026-03'

-- prunes well: bare column, half-open range
WHERE pickup_ts >= '2026-03-01' AND pickup_ts < '2026-04-01'
Load data in the order you filter by (for example, by date), or cluster the table as covered in step 3. Verify with Partitions scanned vs. Partitions total.
Join on the clustered column
When a large table is clustered on a column, joining on that column (and repeating the range filter on both sides) lets Snowflake prune partitions of the big table during the join instead of scanning it fully.
					SELECT t.driver_id, SUM(p.amount)
FROM   trips t                          -- clustered on trip_date
JOIN   payments p
  ON   p.driver_id = t.driver_id
  AND  p.trip_date = t.trip_date        -- clustered column in the join
WHERE  t.trip_date >= '2026-03-01' AND t.trip_date < '2026-04-01'
GROUP  BY 1;
Precompute repeated aggregations
If dashboards repeatedly aggregate billions of rows to the same daily or weekly grain, compute that once and query the rollup. Dynamic tables keep it fresh automatically; materialized views and scheduled tasks are alternatives.
					CREATE DYNAMIC TABLE daily_city_rides
  TARGET_LAG = '1 hour' WAREHOUSE = transform_wh AS
SELECT trip_date, city, COUNT(*) AS trips, SUM(fare_amount) AS gross_fares
FROM   rides.trips
GROUP  BY 1, 2;
The trade-off is refresh compute and storage, so it pays off when the rollup is read far more often than it is rebuilt.
Also Read: Stridely Powers Rapid Snowflake Migration for Building Materials Company
Untangle overly complex SQL
Long CTE chains, views stacked many layers deep, and needless subqueries inflate compilation time and give the optimizer more ways to go wrong. Remove joins whose columns are never used, collapse redundant layers, and for expensive intermediate results write a temporary table (or dynamic table) so later steps start from materialized data. If compilation_time is a large share of the total, this is your fix, not a bigger warehouse.
Shrink the data before you join it
Filter and aggregate as early as possible, before joins and window functions, so every later operator handles fewer rows. Do not rely on the optimizer to push every filter down through complex logic.
					-- joins 2B trips, then aggregates
SELECT d.city, SUM(t.fare_amount) FROM trips t JOIN drivers d USING (driver_id) GROUP BY 1;

-- pre-aggregate the big side first
WITH t AS (SELECT driver_id, SUM(fare_amount) AS fare
           FROM trips WHERE trip_date >= '2026-03-01' GROUP BY 1)
SELECT d.city, SUM(t.fare) FROM t JOIN drivers d USING (driver_id) GROUP BY 1;
For incremental pipelines, process only new data (streams, watermarks) rather than recomputing history.
Sometimes repeat a CTE instead of sharing it
A CTE referenced several times may be computed once and reused, which is usually good. But when each reference needs a different slice, a shared result can block per-reference filtering and pruning. Defining the CTE separately for each use lets each copy be filtered and pruned on its own.
					-- shared CTE: computed once for both uses
WITH ev AS (SELECT * FROM app_events)
SELECT ... FROM ev WHERE event_type = 'app_open'
UNION ALL
SELECT ... FROM ev WHERE event_type = 'booking';

-- repeated: each branch scans and prunes only what it needs
SELECT ... FROM app_events WHERE event_type = 'app_open'
UNION ALL
SELECT ... FROM app_events WHERE event_type = 'booking';
Test both versions and compare runtime and bytes scanned. Neither is always faster.
Also read: Snowflake vs Databricks: Which Platform Is Better for Enterprise Data Modernization?
Drop sorts nobody needs
Sorting is memory-hungry and a common cause of spilling. An ORDER BY inside a CTE, view or subquery that is later joined or aggregated is wasted work, since order is not preserved. Sort once, at the outermost query, and only if the consumer needs it.
					WITH t AS (SELECT * FROM trips ORDER BY pickup_ts)   -- pointless sort
SELECT rider_id, COUNT(*) FROM t GROUP BY 1;

-- sort only the final result; ORDER BY ... LIMIT is fine
SELECT rider_id, COUNT(*) AS n FROM trips GROUP BY 1 ORDER BY n DESC LIMIT 100;
Replace self-joins with window functions
Joining a table to itself to find the latest row, a previous value, or a running total reads it twice and can multiply rows. A window function does it in one pass.
					-- self-join: latest trip per rider
SELECT t.* FROM trips t
JOIN (SELECT rider_id, MAX(pickup_ts) AS mx FROM trips GROUP BY 1) m
  ON t.rider_id = m.rider_id AND t.pickup_ts = m.mx;

-- single pass with QUALIFY
SELECT * FROM trips
QUALIFY ROW_NUMBER() OVER (PARTITION BY rider_id ORDER BY pickup_ts DESC) = 1;
Use LAG/LEAD for row-to-previous-row comparisons and SUM() OVER for running totals.
Split OR joins into separate joins
An OR across different columns in a join condition prevents an efficient hash join and can degrade into something close to a Cartesian comparison. Split it into one join per condition and combine with UNION ALL, excluding overlap so rows are not duplicated.
					SELECT t.trip_id, d.name FROM trips t
JOIN drivers d ON t.assigned_driver_id = d.id OR t.previous_driver_id = d.id;

SELECT t.trip_id, d.name FROM trips t
JOIN drivers d ON t.assigned_driver_id = d.id
UNION ALL
SELECT t.trip_id, d.name FROM trips t
JOIN drivers d ON t.previous_driver_id = d.id
WHERE t.assigned_driver_id IS DISTINCT FROM t.previous_driver_id;
Conclusion: scalability with financial discipline
Elastic compute without observability leads to runaway spend. Check queue time, spilling, pruning and join behavior first, apply the query-level fixes above, and resize only when the profile shows pure CPU work on large volumes.
FAQs
What is Snowflake Query Optimization, and why is it important for enterprise data teams?
When should organizations invest in Snowflake performance optimization and consulting services?
How does data warehouse architecture impact Snowflake query performance?
How can Snowflake Query Optimization support AI and Generative AI initiatives?
Author Bio
Harsh Shah is a Technical Project Lead with 14 years of experience in BI, analytics platforms, database architecture, data engineering, and modern cloud data technologies. His expertise includes Snowflake, Databricks, SQL optimization, data warehousing, and data migration, with a focus on building scalable and high-performance analytics solutions.